Jingdong Zhang

张靖东

Personal Website

Scroll

I am currently a fourth-year Ph.D. student majoring in Computer Science at Texas A&M University, advised by Prof. Wenping Wang and Prof. Xin Li.

I spent several wonderful summers interning in industry. In summer 2026, I was a research intern at NVIDIA Research, working with Chris Choy. I also collaborated with Dr. Xiaohang Zhan and Lingzhi Zhang at Adobe.

I received my Bachelor of Engineering degree at Fudan University in 2023. I also worked as a research assistant at HKUST CSE with Prof. Dan Xu. Previously, I worked with Profs. Tao Chen and Jiayuan Fan.

My research builds scalable foundation models for spatial intelligence, with interests in:

  • Spatial reasoning & scene understandingPerceiving and reasoning about the world from visual observations, toward embodied spatial intelligence.
  • Multi-modal learningVision-language models and agentic systems that ground, search, and reason across modalities.
  • Generative modelsControllable generation and editing of images, videos, shapes, etc.

News

  • Sep. 2026: I am on the job market! Actively looking for both full-time and internship positions.
  • Sep. 2026: Beyond Thinking has been accepted by NeurIPS 2026!
  • Apr. 2026: MTPano has been accepted by SIGGRAPH 2026!
  • Feb. 2026: UniSER has been accepted by CVPR 2026!
  • Dec. 2025: Will be joining NVIDIA Research in 2026 summer!
  • Aug. 2025: SPGen has been accepted by SIGGRAPH Asia 2025!
  • May. 2025: Start the research internship in Adobe!
  • Jan. 2025: HiTTs has been accepted by ACM MM 2025!
  • Jan. 2025: BridgeNet has been accepted by TPAMI!
  • May. 2024: Start the research internship in Tencent America!

Internship

NVIDIA Research

Research Intern, working on foundational spatial understanding.

May 2026 - Aug 2026
Adobe

Research Intern, working on generative soft inpainting.

May 2025 - Aug 2025
Tencent America

Research Intern, working on high-quality 3D asset generation.

May 2024 - Aug 2024

Publications

S4VY demo

S4VY: Segment Anything in Feed-Forward 4D Visual Geometry

Under review, 2026 arxiv project

Abstract: We present S4VY, a Segment Anything model that establishes object identities through shared 4D visual geometry instead of propagating 2D masks along ordered frames: i) Feed-forward Segment Anything in 4D: persistent object queries turn shared visual-geometric features into exhaustive class-agnostic 4D instances, each keeping one identity across all observations, and any of them can be selected by point or box prompts, ii) Agentic language grounding: a dual-stream grounder, active tree search and a comparative critic locate natural-language targets across large dynamic observation sets.
Imagining in 360 demo

Beyond Thinking: Imagining in 360 for Humanoid Visual Search

NeurIPS, 2026 arxiv

Abstract: We propose Imagining in 360, a framework for Humanoid Visual Search (HVS) in immersive 360 environments with: i) Decoupled paradigm: separates intuitive spatial imagination from action planning for more grounded exploration, ii) Probabilistic Imaginator: learns spatial priors and guides the Actor via probabilistic estimations, iii) Scalable data engine: a fully automated pipeline producing 1.92M training samples without manual trajectory labels.

MTPano demo

MTPano: Multi-Task Panoramic Scene Understanding via Label-Free Integration of Dense Prediction Priors

Abstract: We propose a foundational panoramic scene understanding model capabale of predicting multiple dense prediction tasks. We achieve this by i) curating large dataset with auto labeling pipeline by existing perspective prediction models, ii) propose PD-BridgeNet to tackle the multi-task interaction challenges under EPR distortions .

HDRI demo

Promoting LDR Panoramas to HDRI with Rendering-Space Losses

SIGGRAPH Poster, 2026 paper project code

Abstract: We promote clipped LDR panoramas to linear HDRIs for image-based lighting: i) a fine-tuned video diffusion model reconstructs the saturated regions, ii) rendering-space losses — a diffuse spherical-harmonic loss and a glossy GGX loss — directly supervise the lighting behavior of the result, recovering light intensity, color and direction.

UniSER demo

UniSER: A Foundation Model for Unified Soft Effects Removal

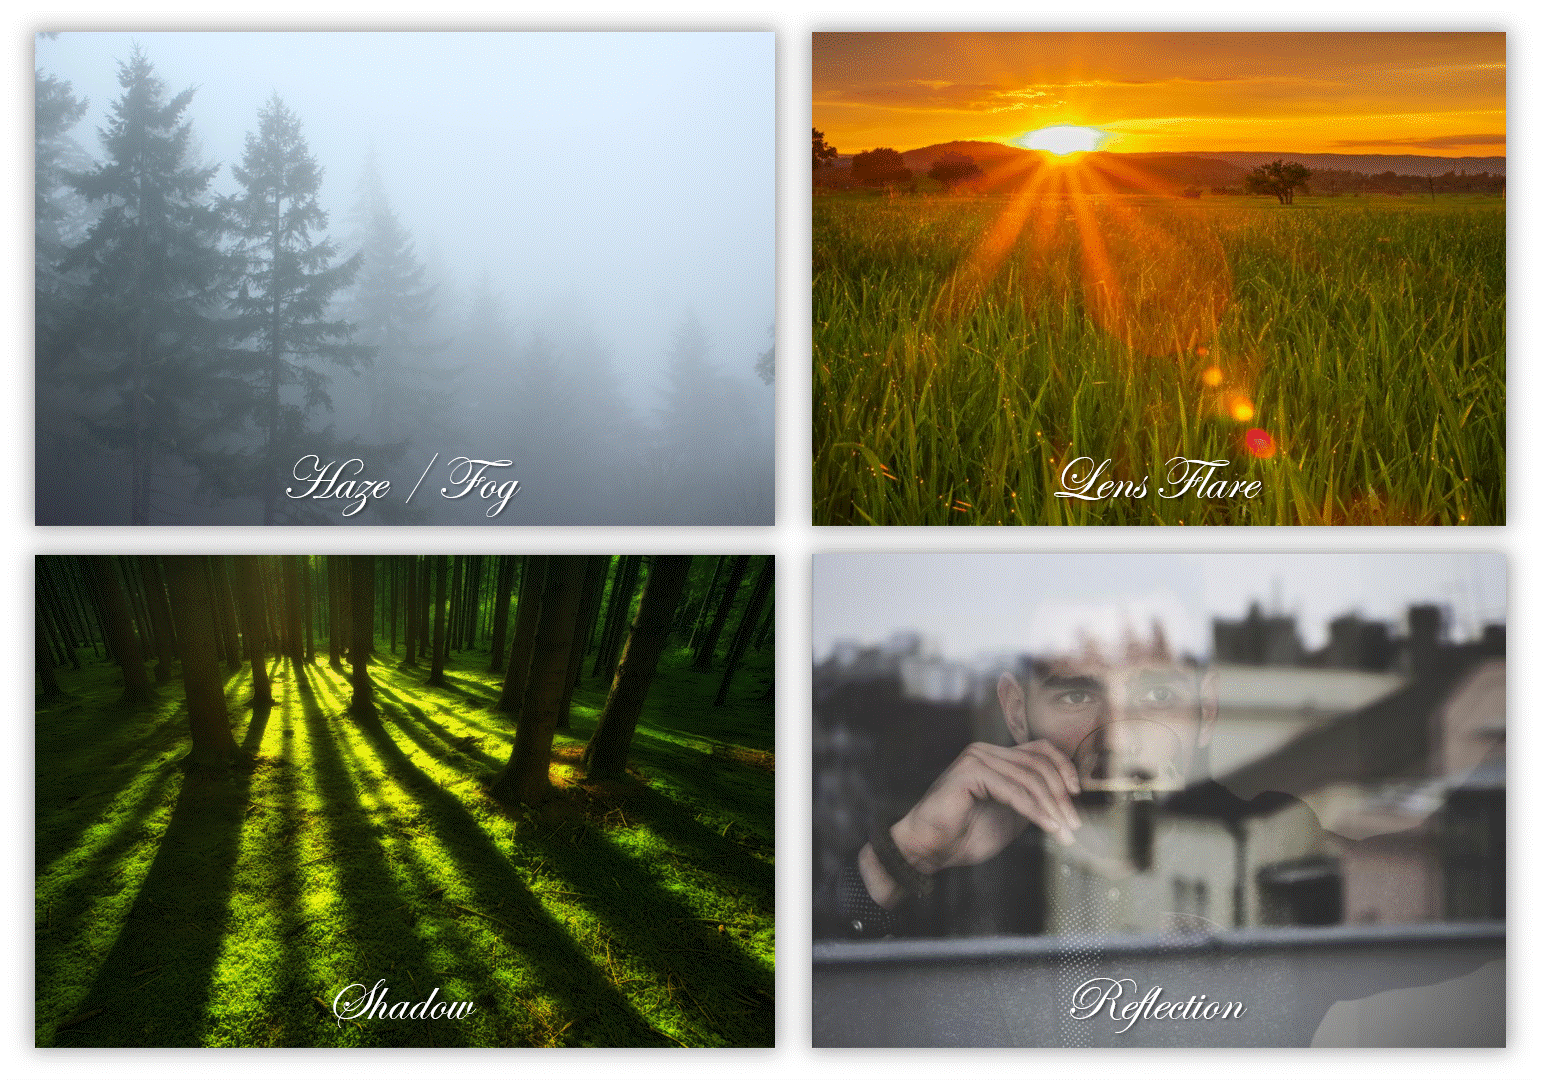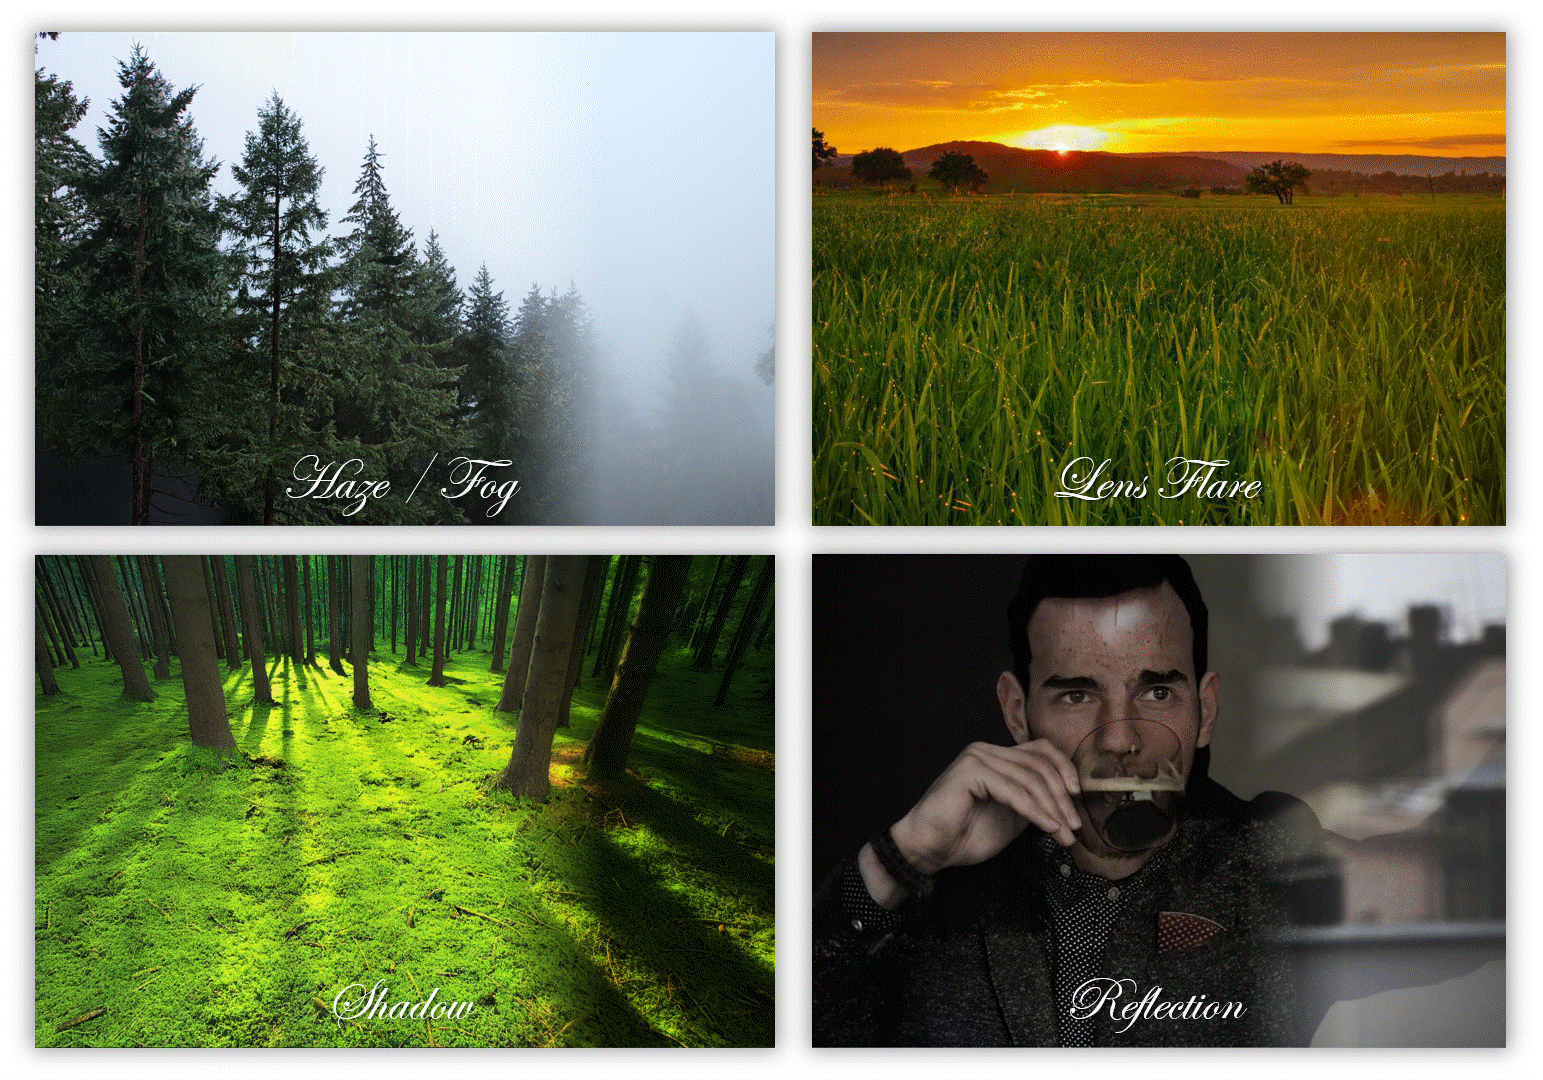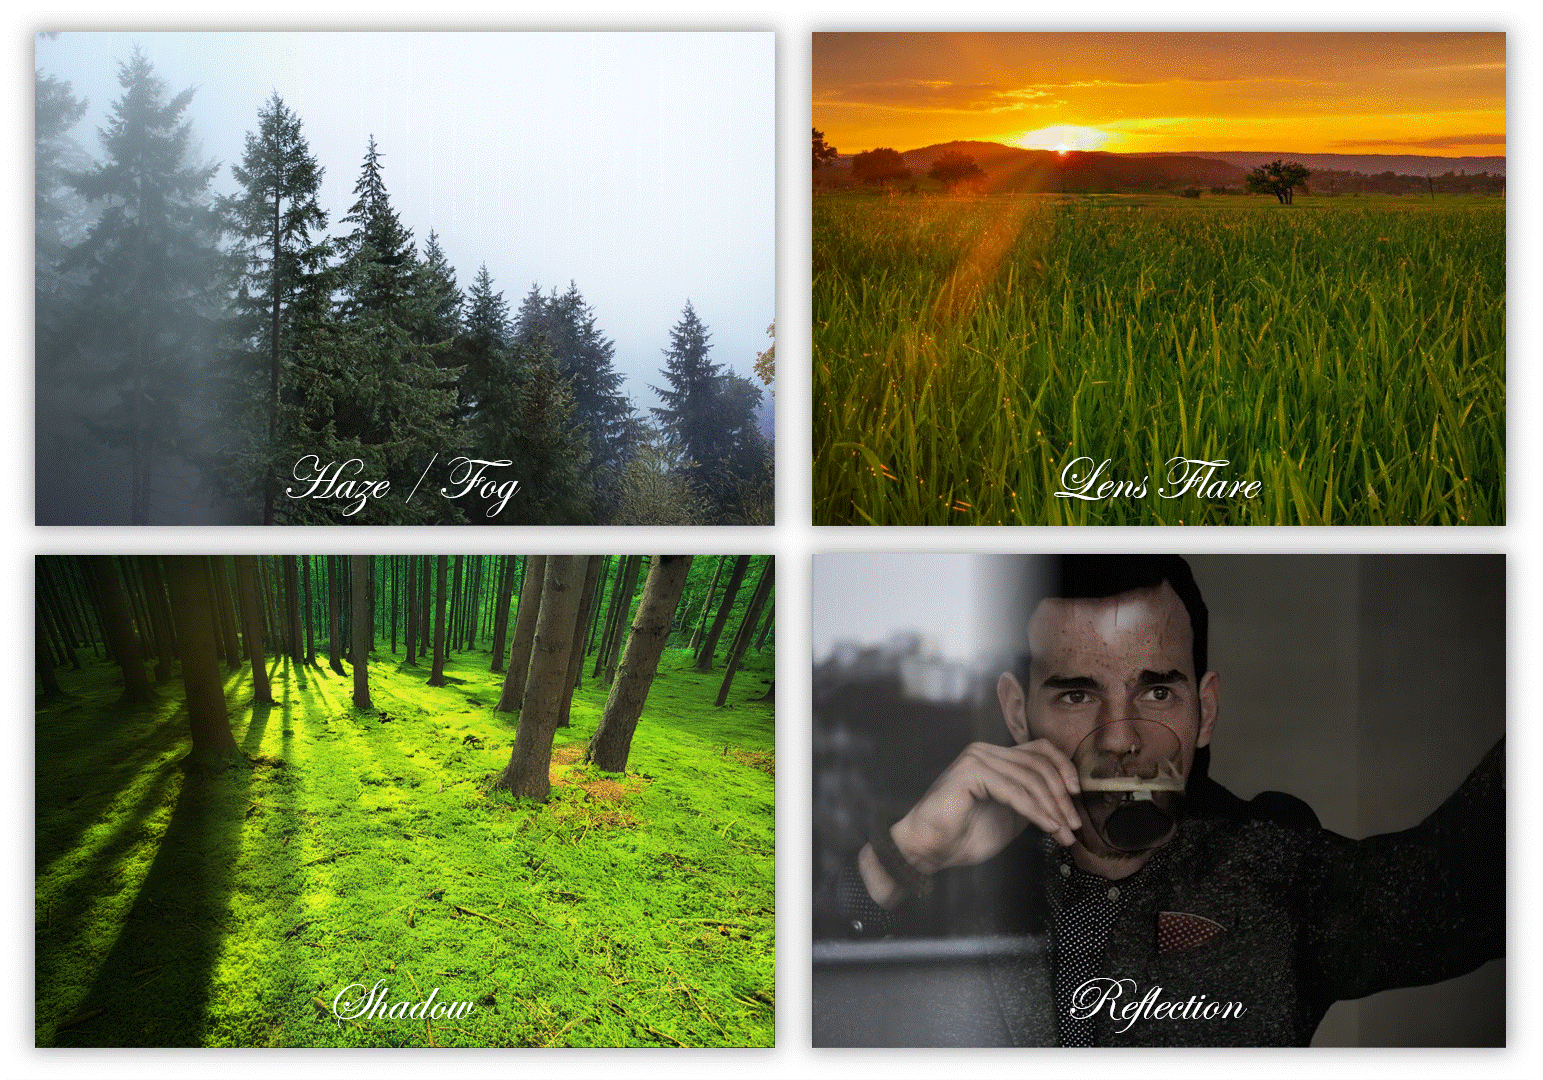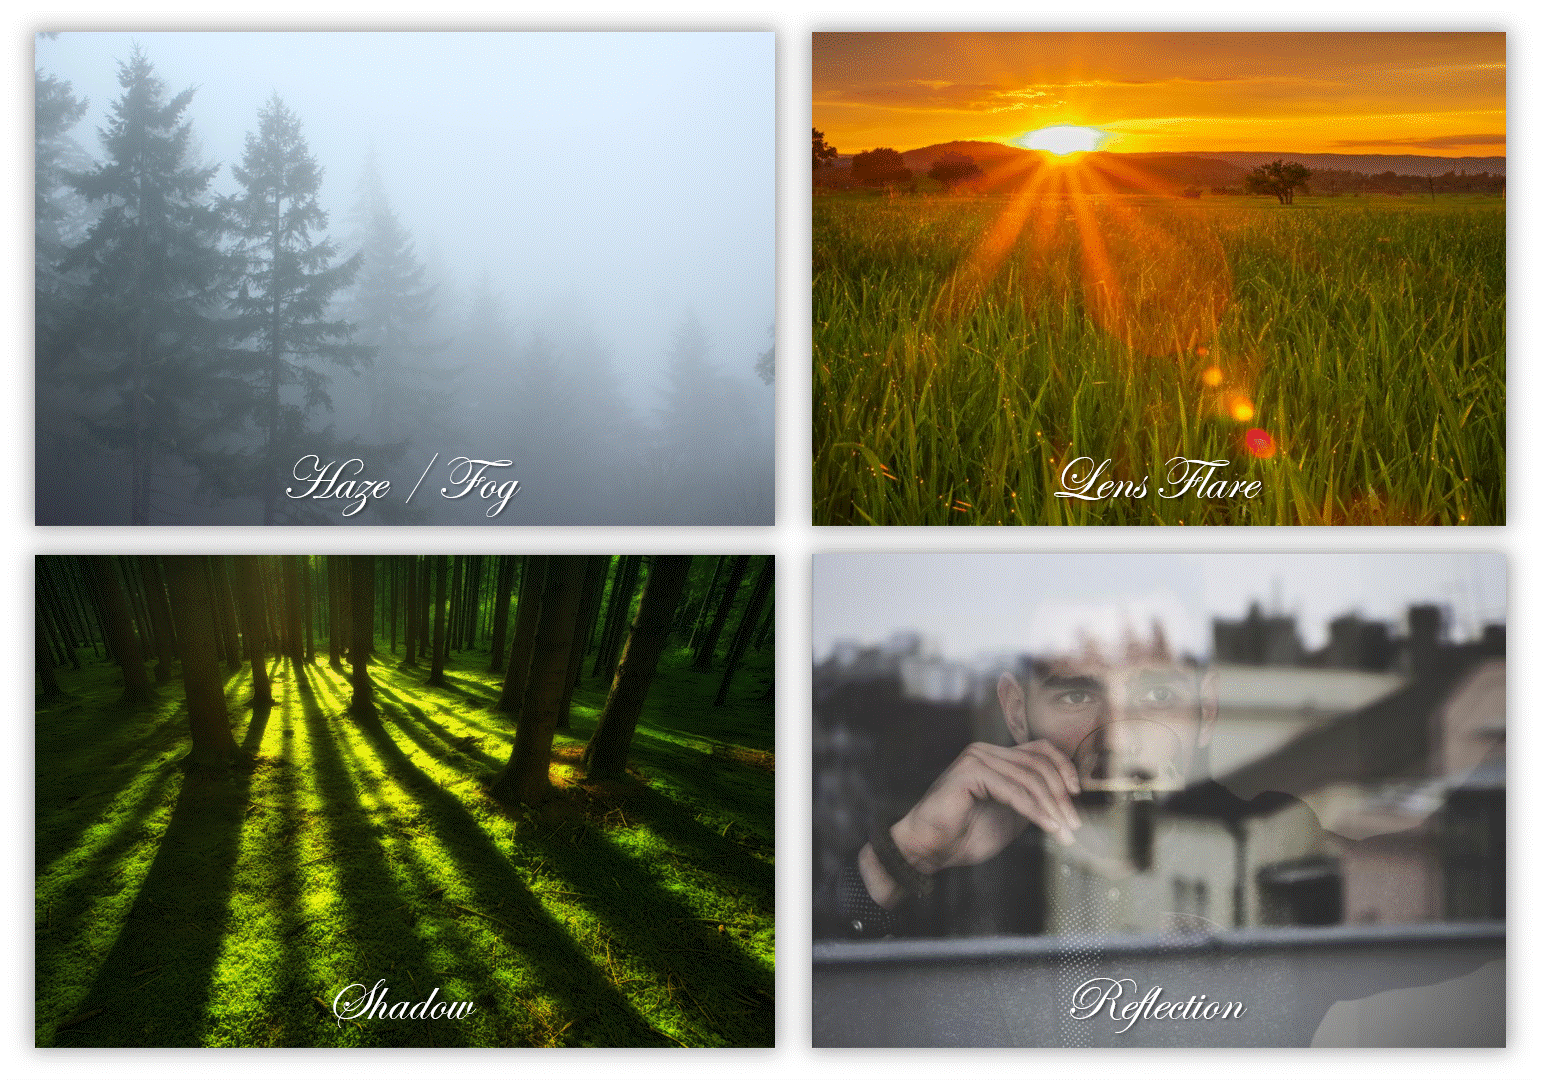
Abstract: We propose a foundational image soft effect removal (SER) model with: i) a large, curated pair-wise dataset with diverse soft effects (e.g. lens flare, haze, shadows, and reflections), ii) fine-grained user control with spatial masks and strength control, iii) generalize on zero-shot unseen effects, iv) add or enhance effects.

SPGen demo

SPGen: Spherical Projection as Consistent and Flexible Representation for Single Image 3D Shape Generation

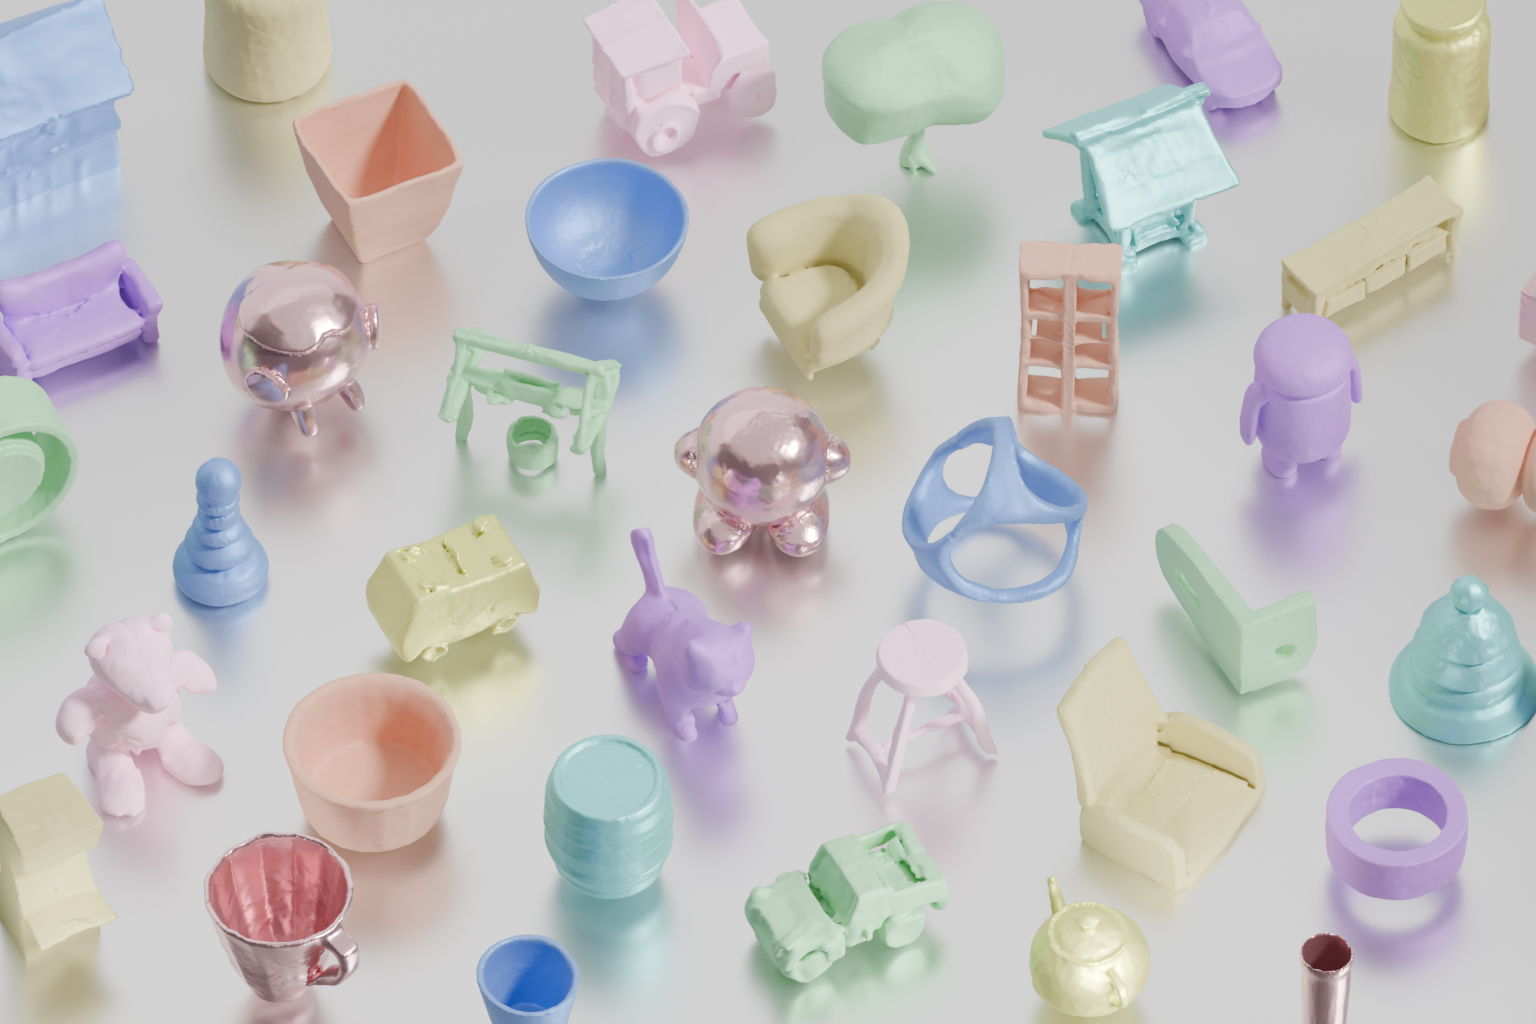
Abstract: SPGen leverages Spherical Projection (SP) to generate high-quality 3D shapes with i) Consistency: SP maps ensure view-consistent and unambiguous 3D reconstruction, ii) Flexibility: Supports arbitrary topologies, iii) Efficiency: Inherit powerful 2D diffusion priors and enables efficient finetuning.

SolidGS demo

SolidGS: Consolidating Gaussian Surfel Splatting for Sparse-View Surface Reconstruction

Arxiv, 2024 arxiv project

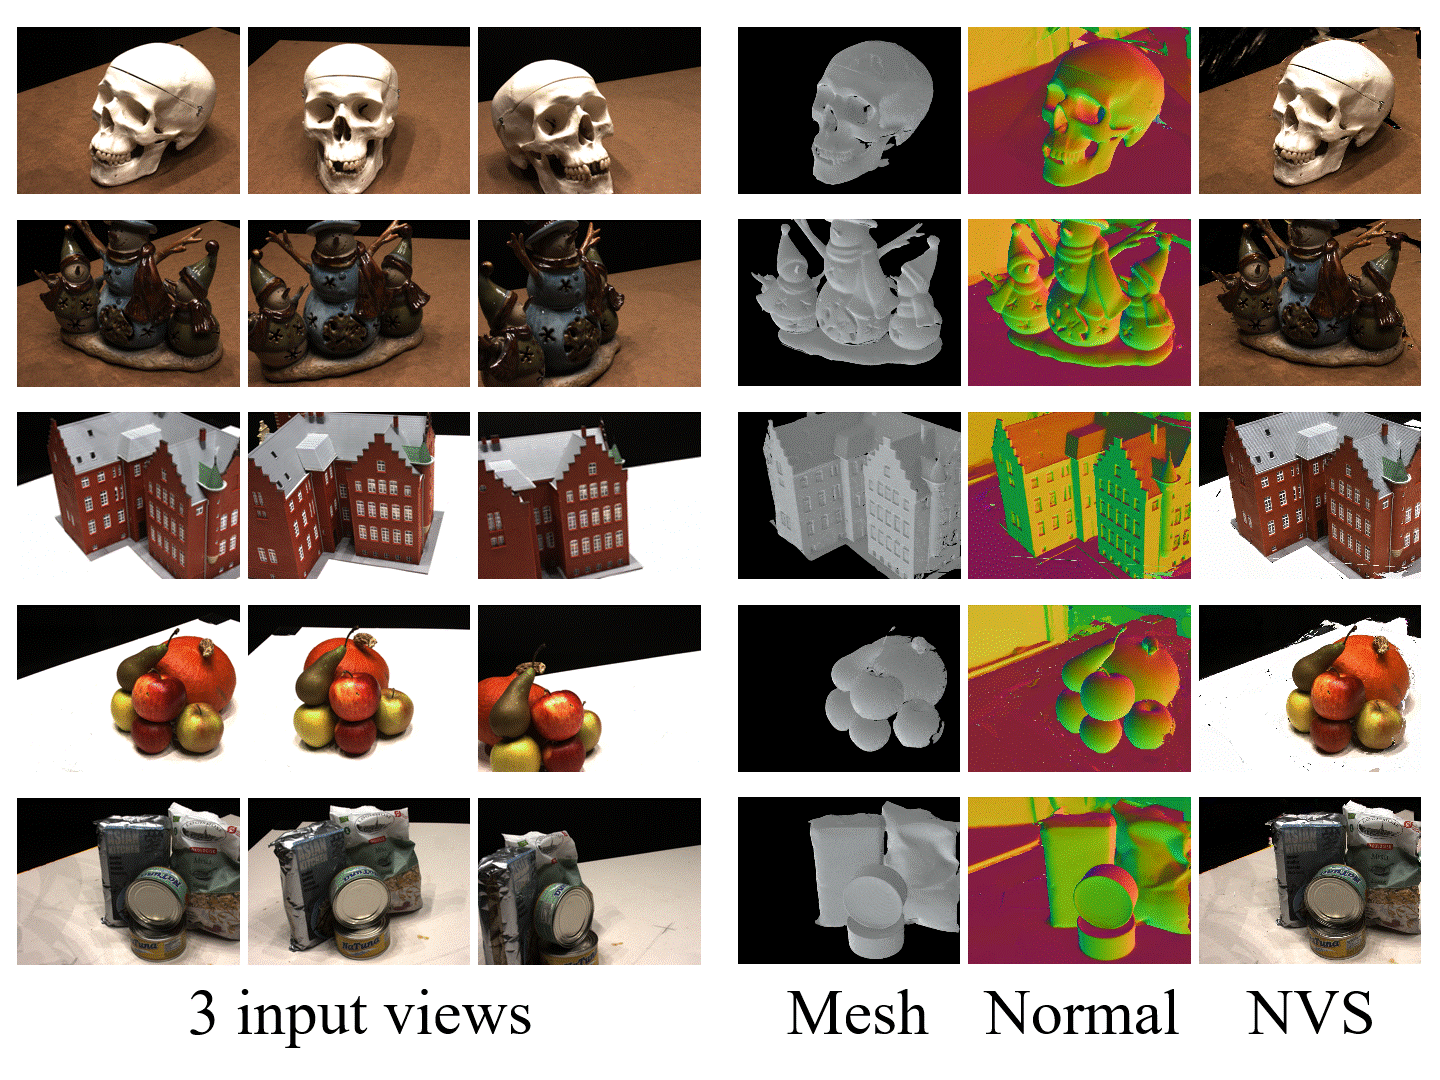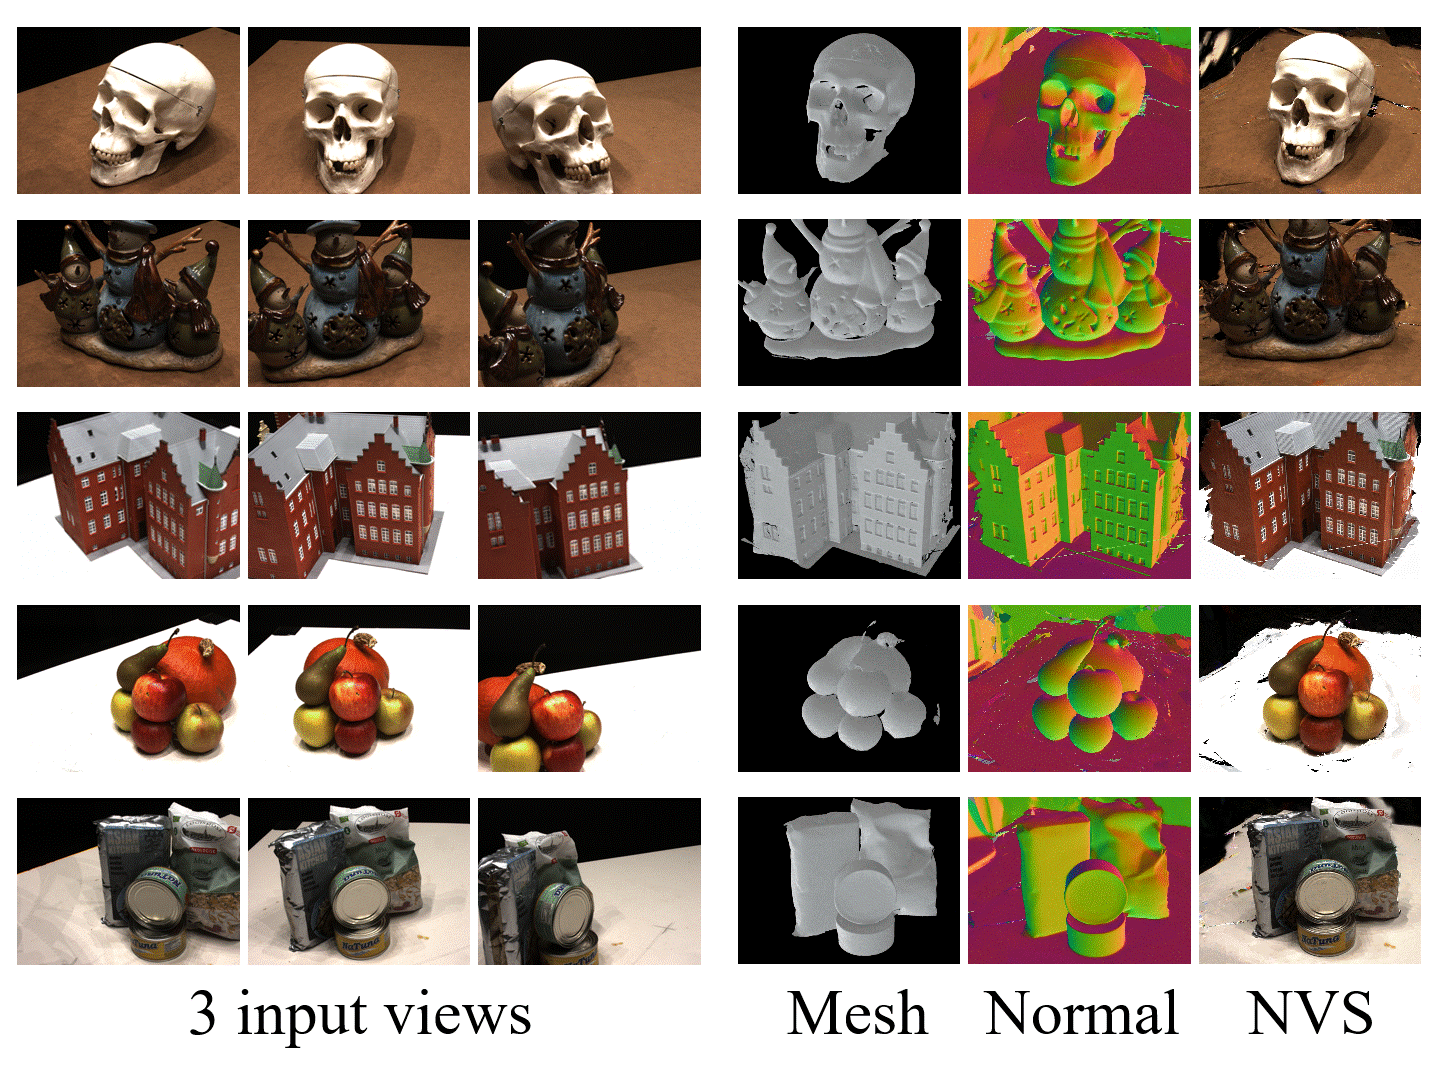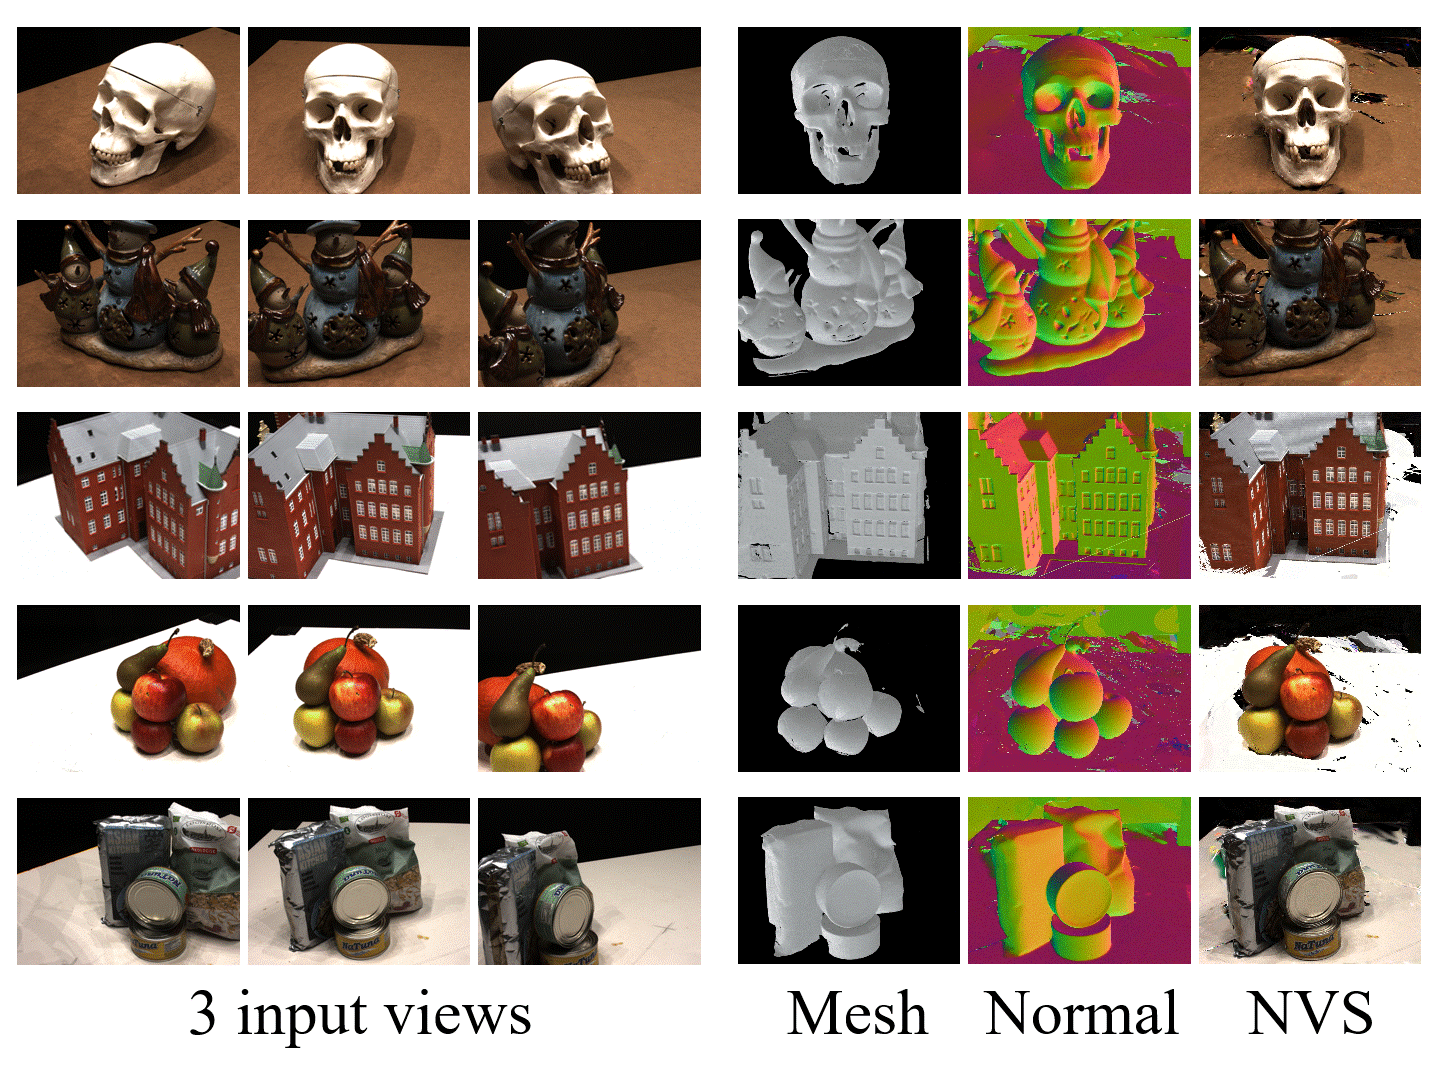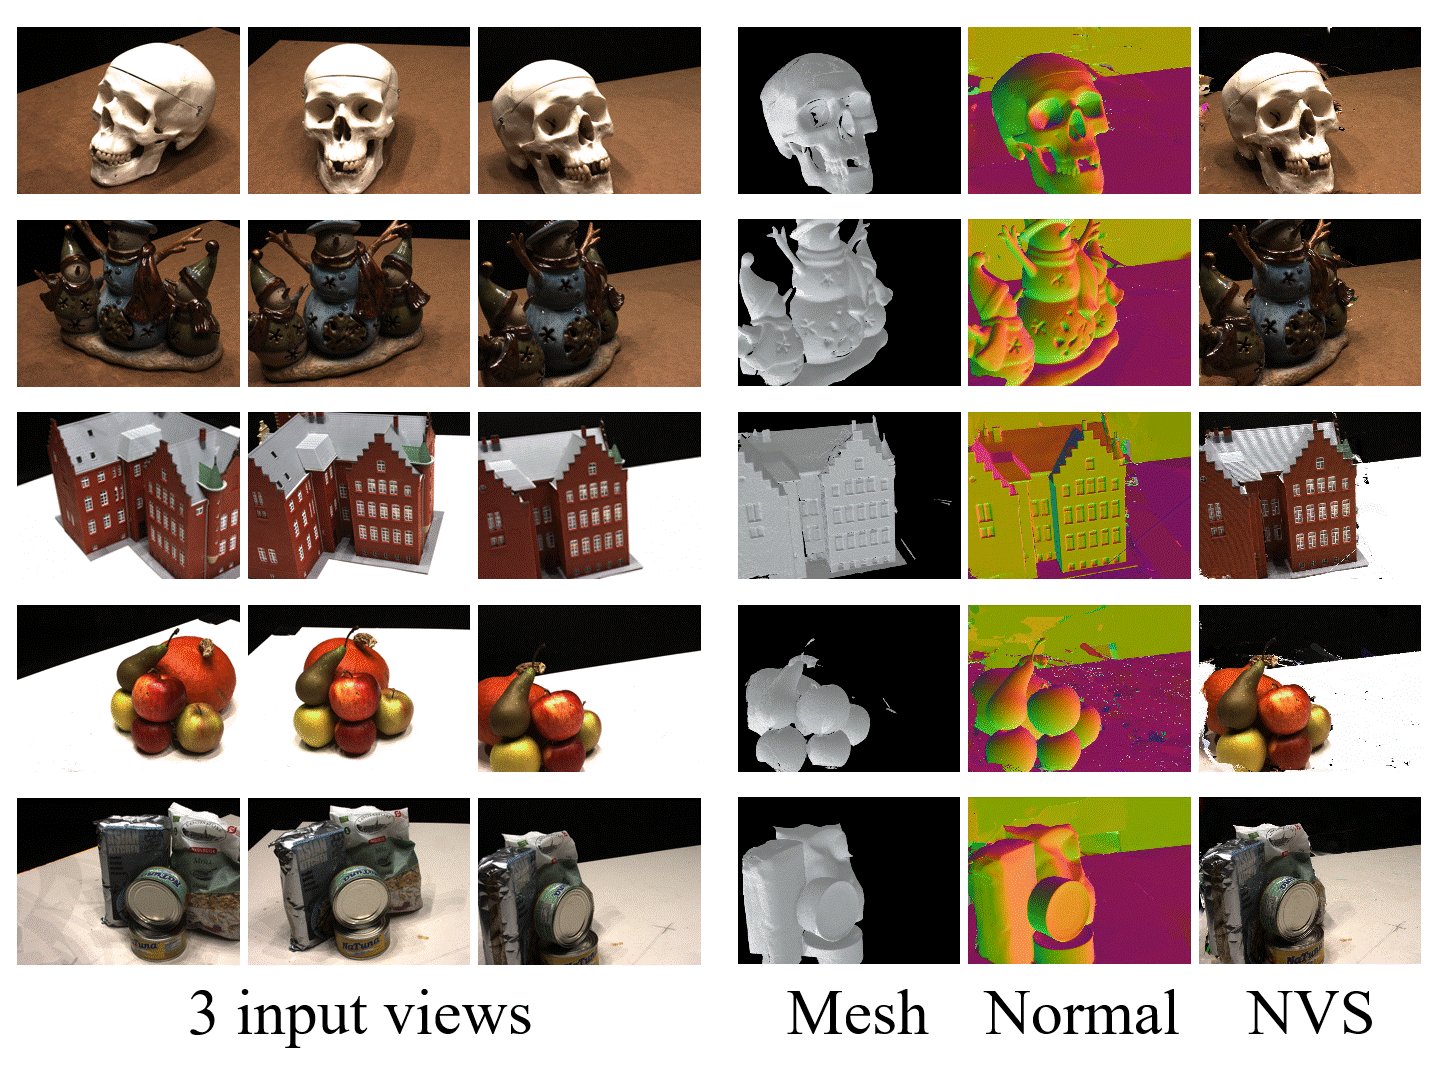
Abstract: We present SolidGS, which reconstructs a consolidated Gaussian field from sparse inputs. Given only three input views, our approach enables high-precision and detailed mesh extraction, and high-quality novel view synthesis, achieved within just three minutes.

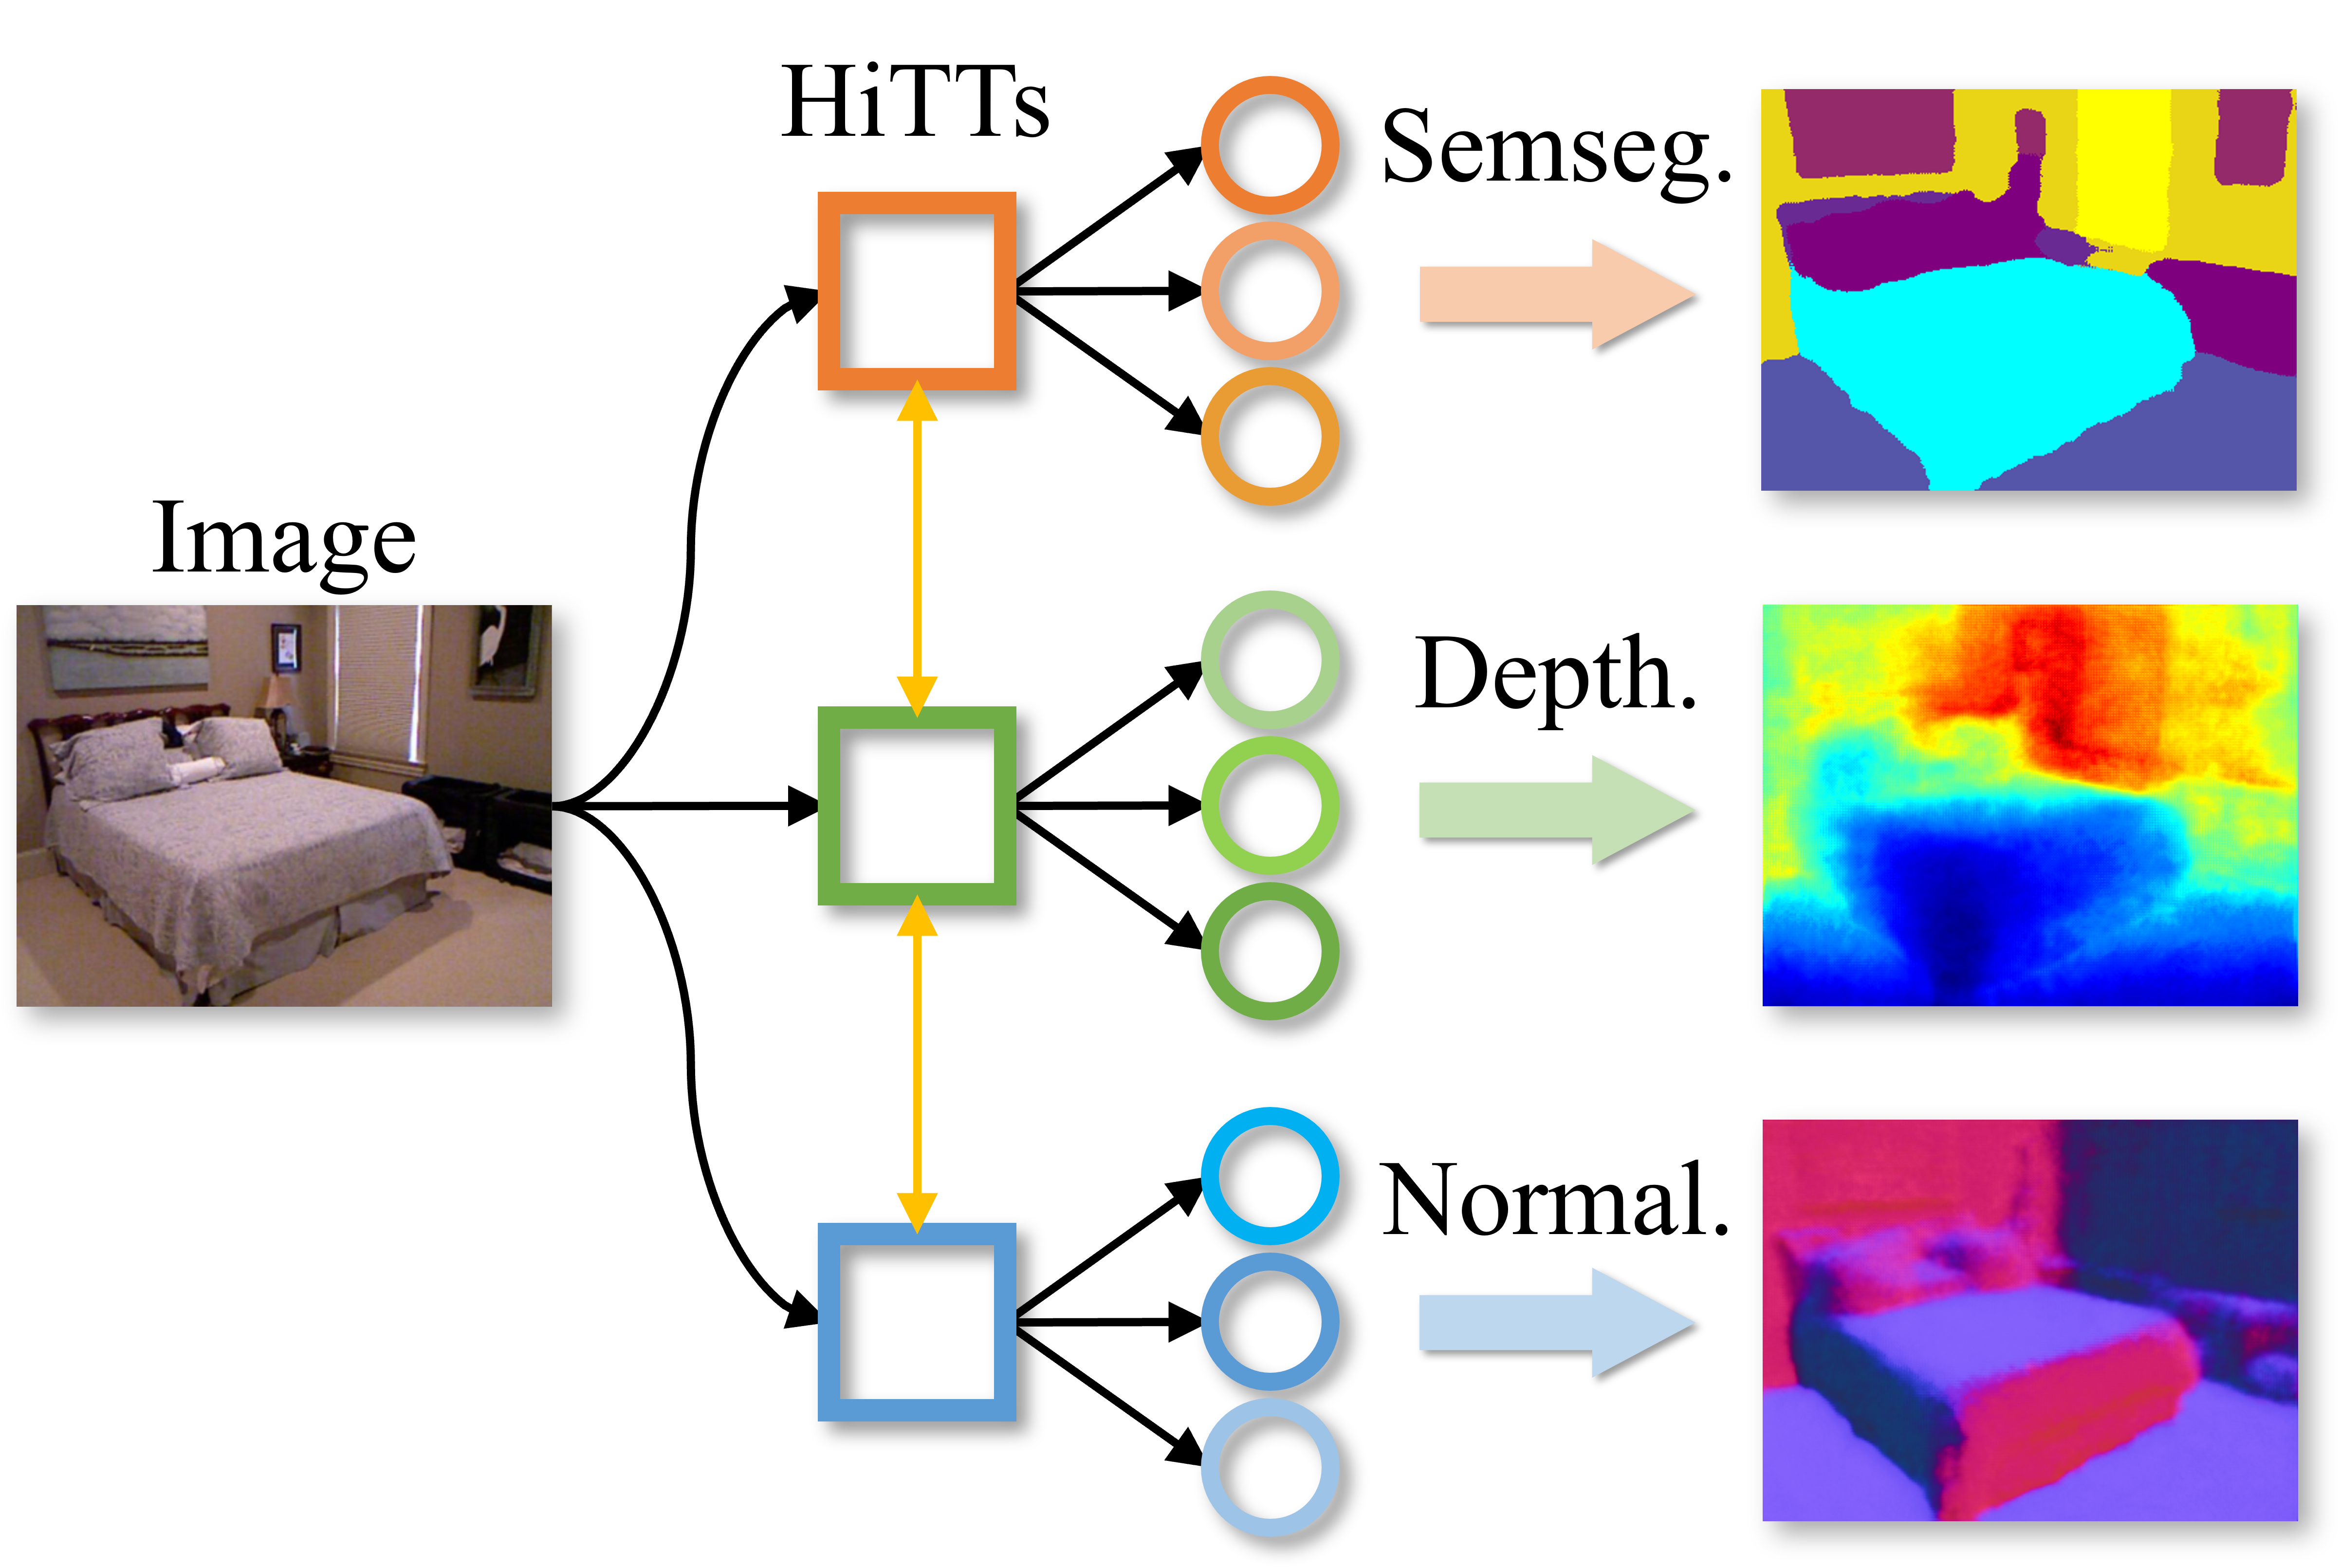
HiTTs demo

Multi-Task Label Discovery via Hierarchical Task Tokens for Partially Annotated Dense Predictions

Abstract: This research proposes a new approach to multi-task dense predictions with partially labeled data. We introduce hierarchical task tokens (HiTTs) to capture multi-level representations. The global task tokens conduct cross-task interactions and transfer knowledge from labeled to unlabeled tasks.

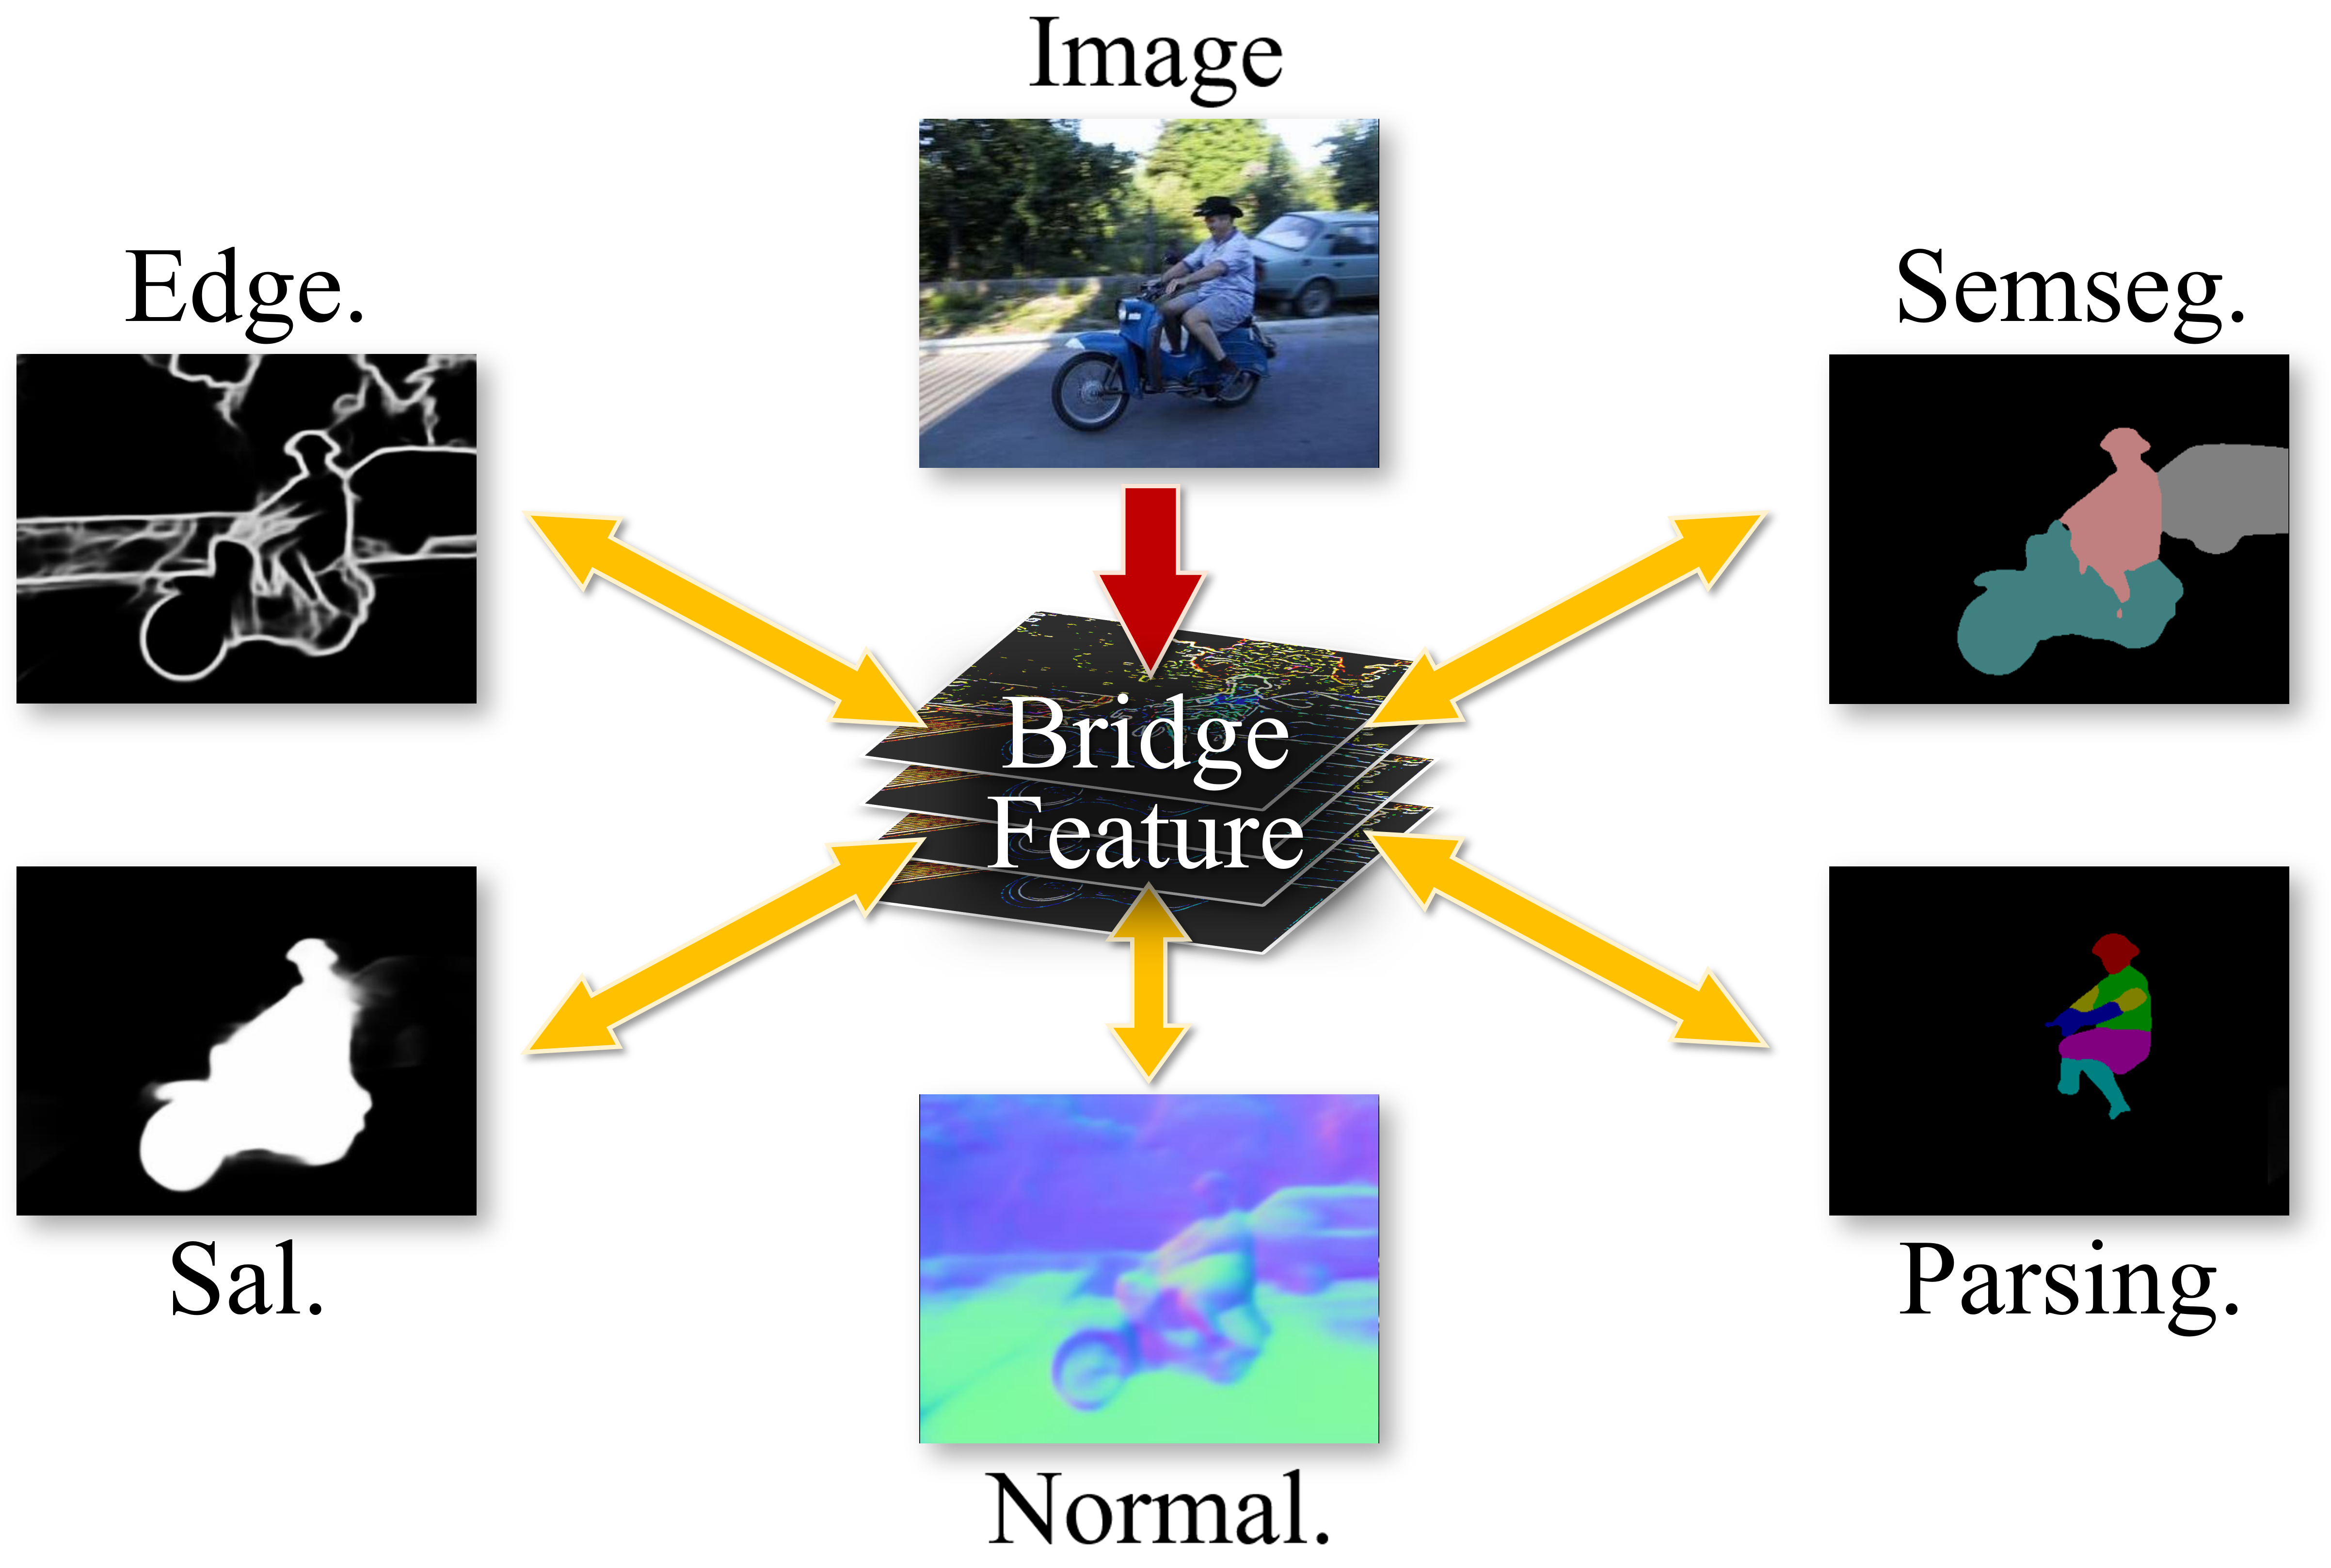
BridgeNet demo

BridgeNet: Comprehensive and Effective Feature Interactions via Bridge Feature for Multi-task Dense Predictions

Abstract: This work introduces a novel BridgeNet for multi-task learning on dense predictions. It uses a Bridge Feature Extractor (BFE) to create strong bridge features and a Task Pattern Propagation (TPP) to solve the task-pattern entanglement issue, resulting in task-specific features with higher quality.

TIP demo

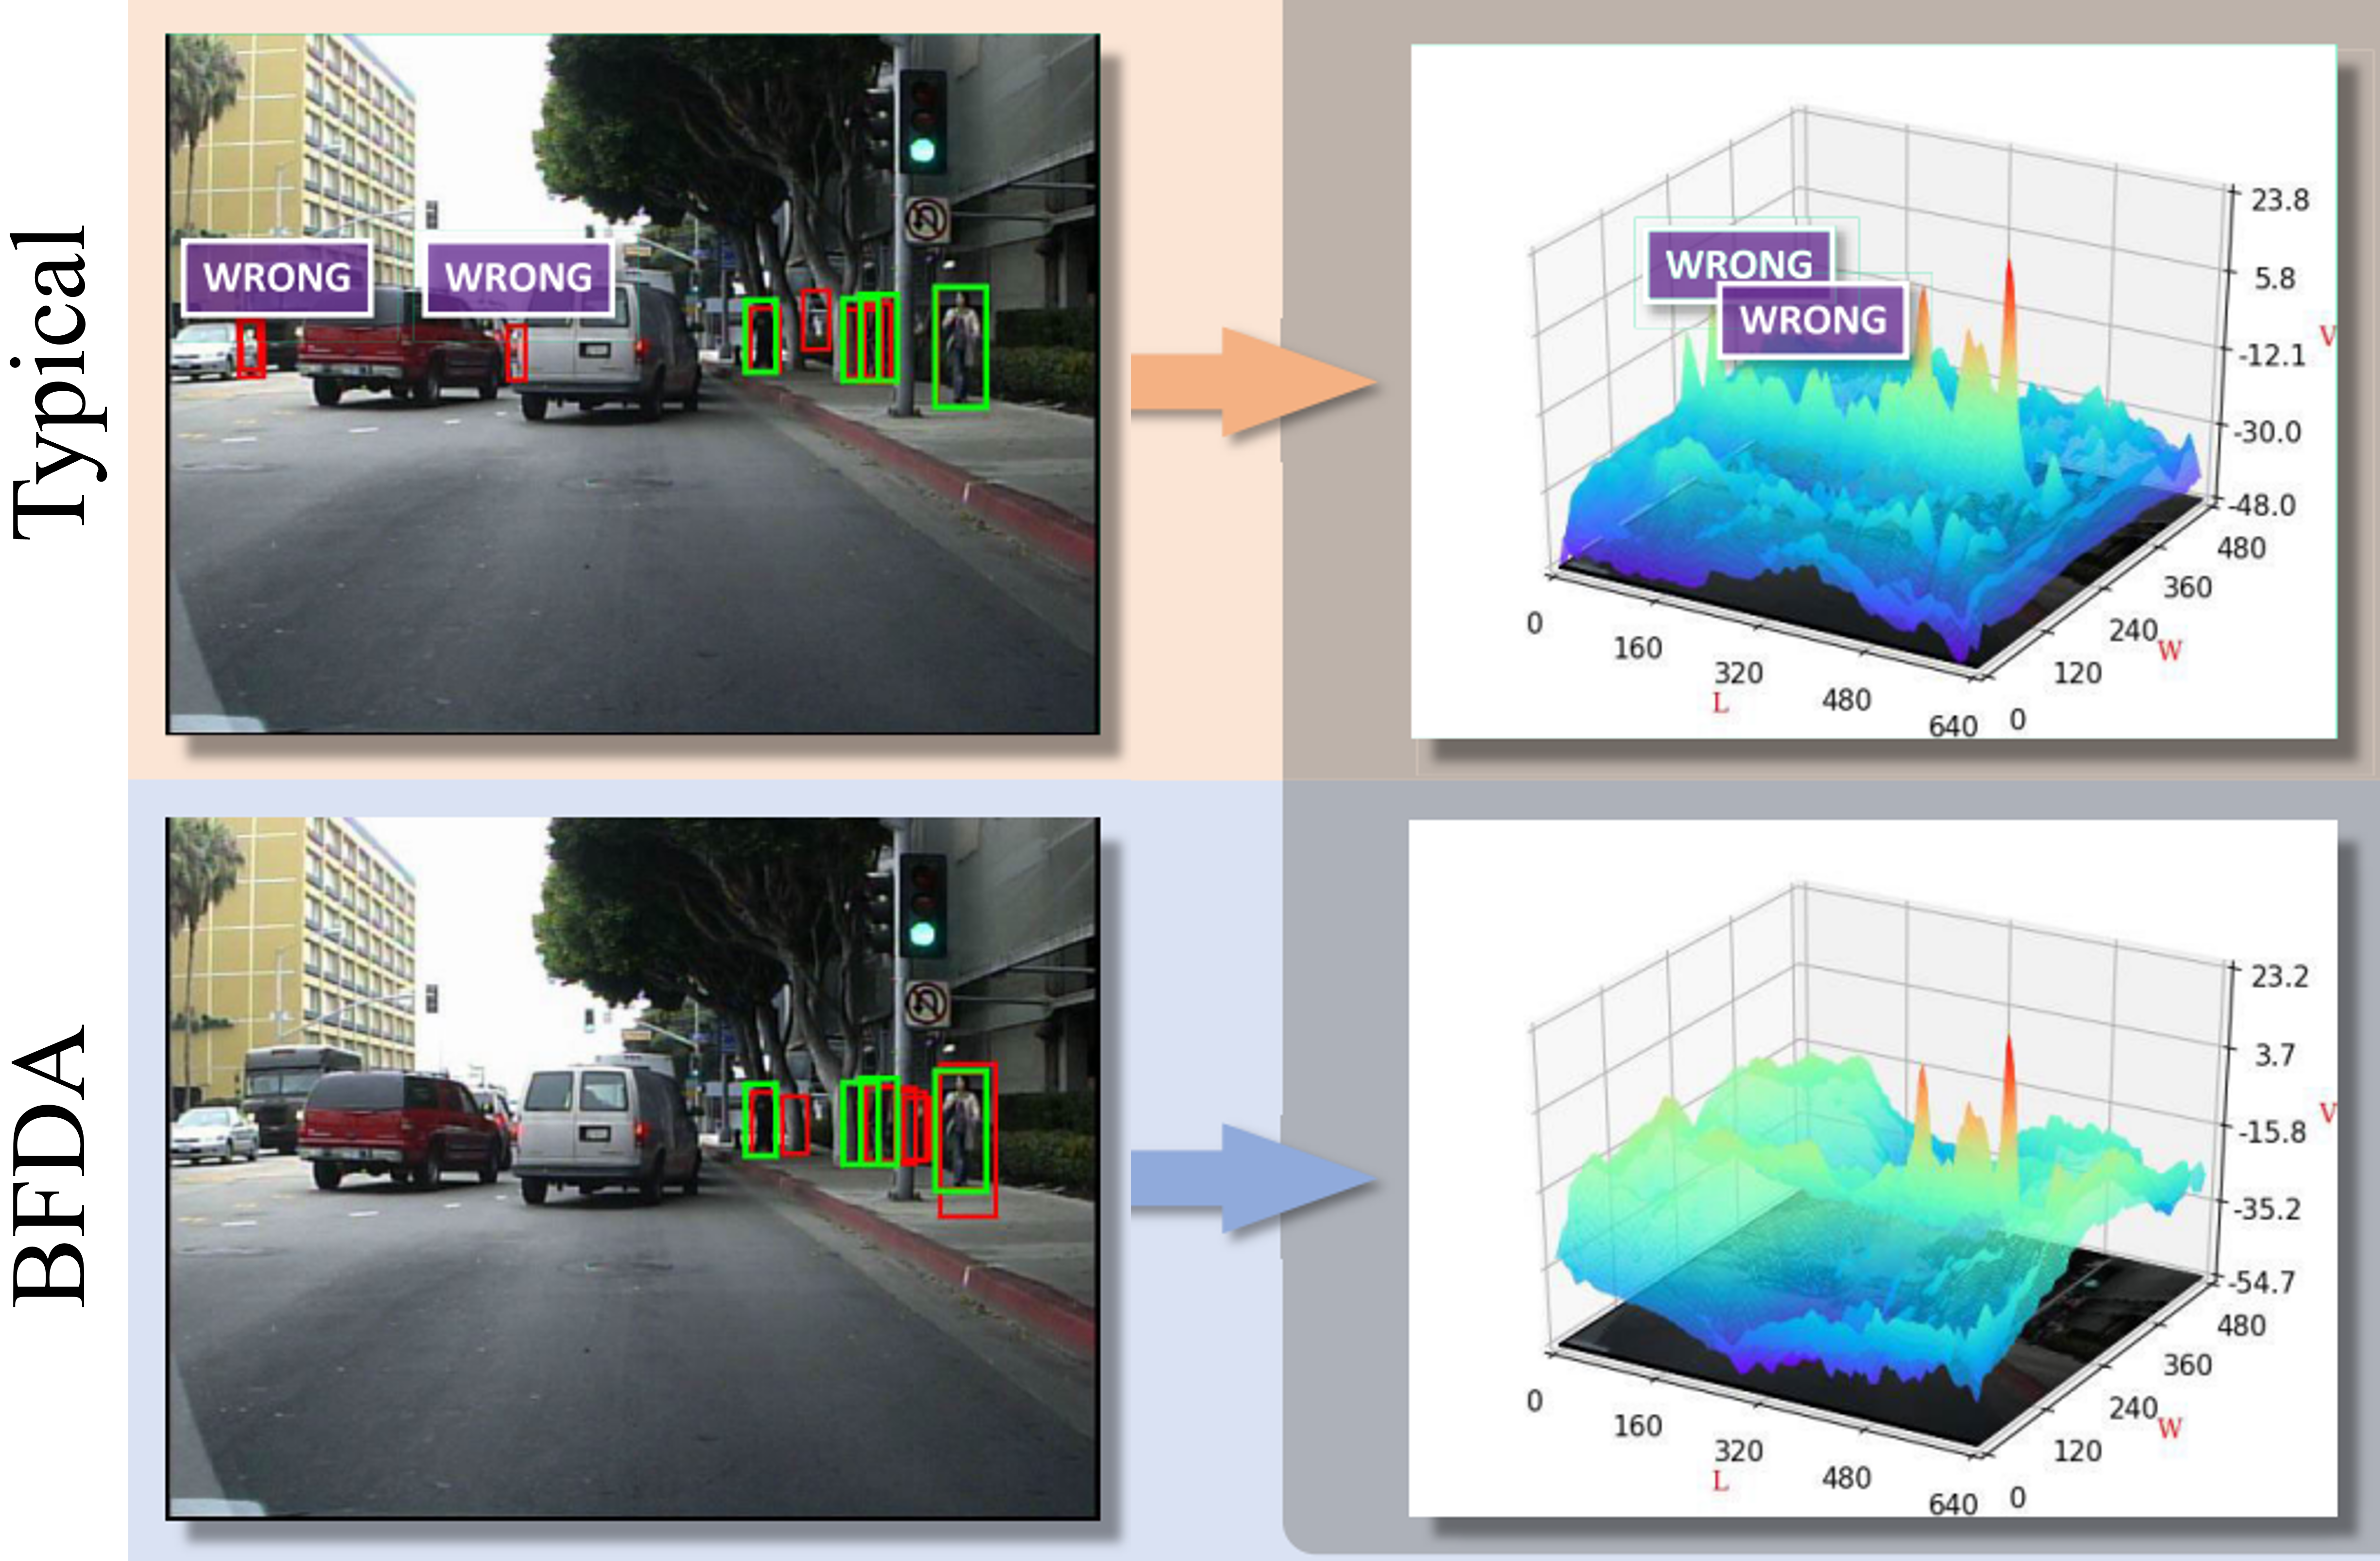
Rethinking Cross-Domain Pedestrian Detection: A Background-Focused Distribution Alignment Framework for Instance-Free One-Stage Detectors

Abstract: We introduce a new approach for cross-domain pedestrian one-stage detectors. The paper identifies a foreground-background misalignment issue in image-level feature alignment, and a novel framework, Background-Focused Distribution Alignment (BFDA) is proposed to address this issue.

Education

Texas A&M University

Department of Computer Science and Engineering

Ph.D. Student

August 2023 - Present
Fudan University

Intelligent Science and Technology (Excellent Class)

Undergraduate Degree

September 2019 - June 2023

Research Experience

  • Jun. 2023 - Present: Ph.D. student, Aggie Graphics Group, Texas A&M University
    Advisor: Prof. Wenping Wang and Prof. Xin Li
  • Feb. 2022 - Present: Research Assistant, HKUST
    Advisor: Prof. Dan Xu
  • Jul. 2021 - Present: Research Assistant, Fudan Embedded Deep Learning and Visual Analysis Lab
    Advisor: Prof. Tao Chen and Prof. Jiayuan Fan

Selected Awards

  • The third prize of outstanding Undergraduate Student Scholarship of Fudan University in 2021-2022.
  • The second prize of outstanding Undergraduate Student Scholarship of Fudan University in 2019-2020.
  • Outstanding Student of Fudan University in 2019-2020.
  • The first prize of Advanced Driving Assistance System (ADAS) National Competition by Dell Corporation, May 2021.

Academic Service & Teaching

Reviewer for:

CVPR, ICCV, ECCV, NeurIPS, ICLR, ICRA, AAAI, TPAMI, TVCG

Teaching Assistant:
  • CSCE 633: Machine Learning
  • CSCE 489: Special Topics in Computer Science and Engineering
  • CSCE 442: Scientific Programming
  • CSCE 222: Discrete Structures for Computing

Miscellaneous

I love photography and road trips. Intermediate skier.